Arjun's Monday in Bandra West: the agent that refunded the wrong order
Arjun is a freelance automation builder in Bandra West, Mumbai, whose clients are small Shopify stores and clinics around Linking Road. One Monday, a client's support-triage agent does something small and expensive: it refunds the wrong order. The customer is happy, the store owner is not, and Arjun gets the call.
He opens the logs. The HTTP log says the request succeeded in 340 milliseconds. Nothing says why the agent chose the refund tool, which order ID it passed, or what the order-lookup tool returned a second earlier. He spends the afternoon re-running the conversation by hand. The bug was never in the final answer. It was in step two of five, where the agent read a search result and picked the wrong record.
Every agent failure Arjun has seen since follows the same shape: the output looks confident, the logs look green, and the decision that caused the damage is invisible. This guide answers the question his Monday raised: is there a free way to watch an agent think, so the next failure takes ten minutes to explain instead of an afternoon?
The failed agent run never explains itself in its final answer. The explanation lives in the steps it took to get there — and if you cannot see those steps, you are debugging blind.
What "why did it fail" actually requires: the trace
Forget product names for a minute. To explain any agent failure you need one connected artifact — the trace — with five parts:
- Step 1 — The prompt. What the agent was told, including system instructions. A vague instruction ("handle refunds helpfully") behaves differently from a precise one ("refund only orders the lookup tool confirms as delivered").
- Step 2 — Each tool call. The tool's name, the exact arguments passed, and the result returned. Most failures hide here: the wrong tool, the right tool with the wrong ID, or a tool error the agent quietly ignored and worked around.
- Step 3 — The reasoning between calls. What the agent concluded from each result before choosing the next step. This is where a plausible-sounding mistake becomes a confident wrong action.
- Step 4 — The final decision. What it did — refund, reply, booking, escalation — and which earlier step justified it.
- Step 5 — The cost and time of each step. Tokens and latency per step: a run costing ten times its budget is a failure even when the answer is right.
Traditional monitoring cannot give you this: it reports a 340-millisecond request and a 200 status, not why the agent called the refund tool instead of the lookup tool. Agent debugging needs a different unit of analysis: the reasoning trace, not the request.
The four failure layers: find the layer before you fix anything
When Arjun reconstructs a failed run, the breakage sits in one of four layers — and each layer has a different fix:
- Step 1 — Retrieval failure. The agent fetched documents, but the wrong ones. It then did its best with bad input. Fix: check the retrieved chunks against the question, and check whether your chunks are too large, too small, or stale.
- Step 2 — Reasoning failure. Retrieval returned the right context, but the model ignored the most relevant part — often because earlier tool outputs filled the context window. Fix: inspect the full context at the synthesis step, not just the query.
- Step 3 — Planning failure. The agent chose the wrong tool: a web search when it should have queried the internal database, or a direct answer when it should have called a calculator. Fix: trace the decision point and read the exact model output at that step.
- Step 4 — Tool execution failure. The agent called the tool, the tool errored or timed out, and the agent carried on anyway without surfacing the failure. Fix: trace each tool call's input, output, latency, and error status separately — and treat a timeout as its own outcome, not as a success, so a retry cannot double-book or double-charge.
Never fix an agent by rewriting its final answer. Fix the first step where it went wrong, change one variable, and re-run the same task to prove the fix.
VQ Agent Console vs LangSmith vs Langfuse: the comparison
Here is the honest table. Prices are vendor pricing pages as compiled in October 2026; treat them as the current list position, not a quote.
| VQ Agent Console | LangSmith | Langfuse | |
|---|---|---|---|
| What it is | Free demo console for an agent loop (THINK → ACT → DECIDE) | Managed LLM/agent observability platform | Open-source LLM observability platform |
| See each step? | Yes — the loop's think, act, and decide steps in a browser tab | Yes — per-step trace waterfall, richest inside LangChain/LangGraph | Yes — traces, sessions, prompt management |
| Evaluations & datasets | No — this is the demo console's real limit | Yes — evals, datasets, prompt playground | Yes — evals, prompt management, experiments |
| Pricing | Free, no seats, no trace meter | Developer free (5,000 traces/month); Plus $39/seat/month with 10,000 base traces, then per-trace usage | Hobby free (50,000 units/month); Core $29/month; self-hosted MIT stack free (your server costs extra) |
| Retention | Demo runs, not a retention story | 14 days base on entry plans; extended retention billed per 1,000 traces | Longer windows on paid tiers; self-hosting keeps your own history |
| Data location | Demo console; the local/offline DECIDE path in VQ Agent Core is the direction of travel, not a compliance certification | US SaaS by default; EU and extended options sit on higher tiers | Self-hosting or EU/US cloud regions; check the plan before relying on it |
| Best for | Learning the loop, debugging one agent's logic, showing a client what an agent does | Production LangChain teams who need evals and deep tracing | Teams who want framework-agnostic tracing and control of their data |
Two rows decide most purchases. LangSmith's depth is real: a G2 reviewer in August 2026 praised its per-step trace waterfall, where each step shows up as a separate span, so debugging means looking at exactly which step failed. Langfuse's independence is also real: it works with any runtime, and self-hosting removes the per-trace meter — at the price of running the infrastructure yourself.
Frameworks are a different purchase: AutoGPT is less actively maintained than OpenHands, LangGraph serves code-first teams, and CrewAI serves multi-agent crews. A console watches an agent run; a framework builds it.
The cheapest observability is the kind you do not have to provision. The most expensive is the kind that bills you per seat and per trace while you are still learning what your agent even does.
What a 5-person team actually pays: the worked math
Take a small team — five people, 20,000 agent runs in a month, each run producing one trace. On published October 2026 rates, as modelled by an independent Langfuse-versus-LangSmith pricing comparison:
- LangSmith Plus: five seats at $39 = $195, plus 10,000 traces above the included allowance at $5 per 1,000 = $50. Total: $245 a month, before retention upgrades or other metered services.
- Langfuse Core: the same workload records 100,000 units (one trace, three observations, one score per run) and stays at the $29 base price.
- VQ Agent Console: $0 — because it is a demo console, not a metered platform. That zero is honest only if you accept what it does not do: no production evals, no dataset regression suites, no retention story.
At higher volume the gap widens on paper: Langfuse's own model puts 500,000 traces (10 spans each, five users, 12-month retention) at $621 on Langfuse Pro versus $3,895 on LangSmith Plus — but that is Langfuse's model, using the extended-retention rate, and LangSmith's SaaS caps retention at 180 days. Treat vendor models as directional, never as invoices. At enterprise scale, one practitioner reports observability reaching 15–20% of the inference budget.
Reviews mining: what real users complain about
The pattern across reviews and practitioner teardowns is consistent:
- LangSmith pricing and retention. A practitioner who ran LangSmith, Langfuse, Helicone, and Phoenix for three months calls LangSmith's pricing "punitive": $39 a seat before a single trace, 14-day default retention, and extended retention at $5 per 1,000 traces with no middle tier. The same teardown notes US-only data unless you are on an Enterprise plan — a real problem for EU teams and GDPR.
- LangSmith debugging friction. The same G2 reviewer who praised the trace waterfall complained that span deduplication is global by span identity, so re-forwarding a trace means remapping every span ID or it silently drops — and that the attribute schema is under-documented, with keys that look equivalent but silently do not work.
- Langfuse gaps. The same teardown praises Langfuse's open source and transparent pricing, then names weak spots: no MCP support for Claude-based tool use, and weak alerting that pushes teams to Datadog or Grafana anyway.
- The proxy trap. Helicone is praised for one-line setup, but it is a proxy, not an instrumentation layer: it sees HTTP traffic, not agent reasoning. If you want to know why an agent made a decision, a proxy cannot tell you.
Every observability tool is honest about what it shows you. The complaints start where the billing model meets the retention window — seats, traces, and days are where free stops being free.
The honest verdict: what VQ Agent Console is not
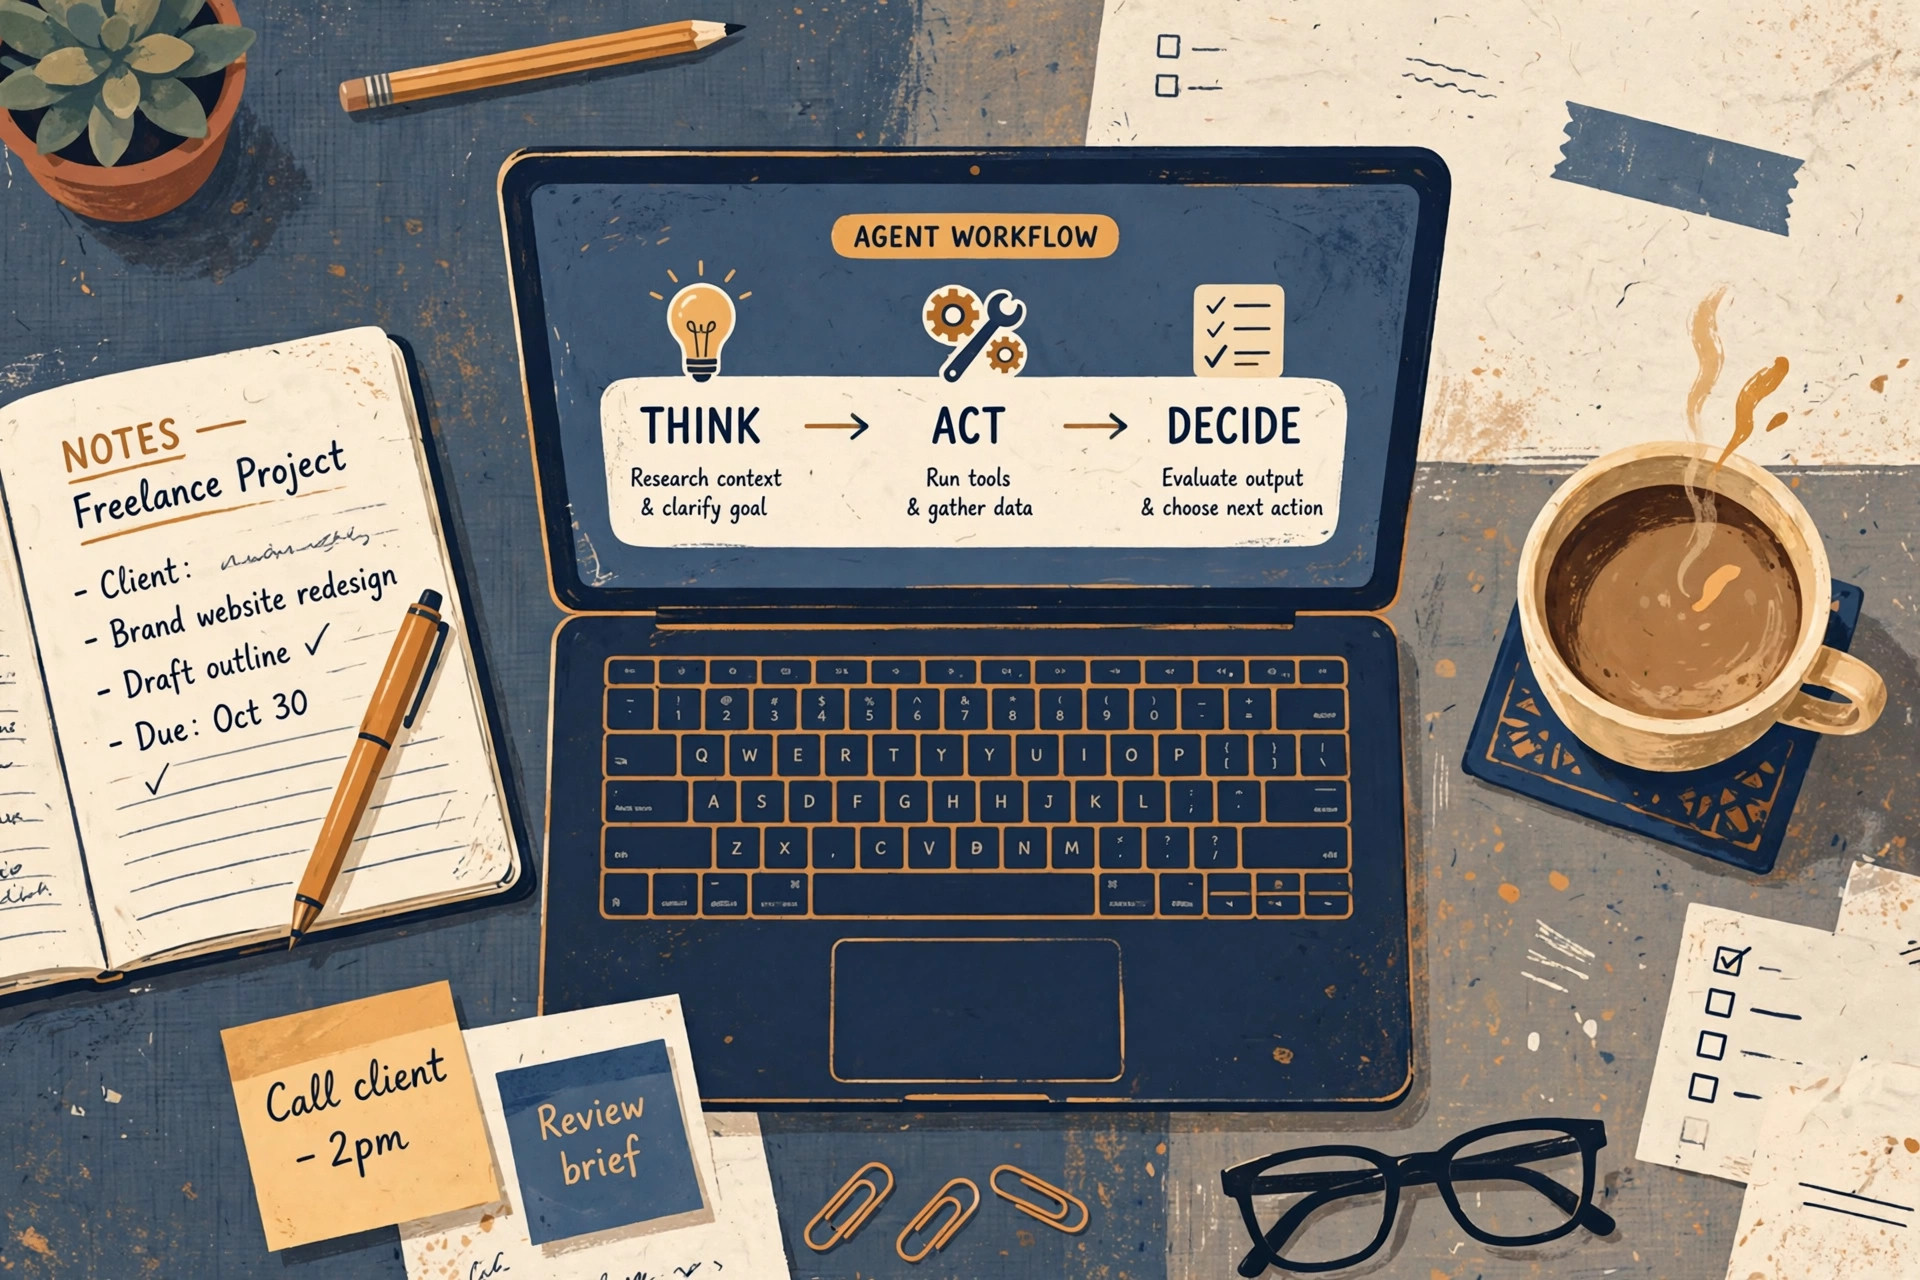
VQ Agent Console is a demo console, and the live page says so itself: every button fires a live POST to your n8n instance and shows the real JSON/TwiML response — scoring, replies, triage, and plans run for real — but WhatsApp, SMS, email, and call delivery need your provider keys (Twilio, Exotel, Gmail) connected first. Its THINK → ACT → DECIDE loop is unusually legible to non-engineers, which is why it works as a learning and debugging tab. It is not a production platform: it does not replace LangSmith's evaluations, Langfuse's prompt management, or either platform's retention and alerting.
So the buying guide is simple:
- Learning or debugging one agent's logic, or showing a client what an agent does: start free with VQ Agent Console. If the trace answers your question, you just saved $195 a month.
- Shipping a production agent on any stack, with data control: self-host Langfuse (free licence, your server bill) or take its $29 Core plan.
- Shipping inside LangChain/LangGraph with evals as the bottleneck: pay for LangSmith Plus and budget the trace overages explicitly — the $245-a-month worked example above, not the $39 headline.
- Running agents at a scale where the meter is the budget: model your real trace volume first. The meter, not the seat price, is what surprises teams.
Try it in 10 minutes: Arjun's debug loop, step by step
- Step 1 — Open the console. Go to https://agentconsole.visionquantech.com/ in a browser tab. No seat, no install, no platform to provision.
- Step 2 — Run a demo scenario. Fire a support-triage scenario and watch the loop: thinks (what it understood), acts (which tool, with what arguments), decides (what it did next) — the real response from the connected workflow, not a canned animation.
- Step 3 — Find the first wrong step. Read top to bottom and stop at the first step you would not have taken. In Arjun's case: the order lookup returned two similar orders, and the agent picked the first instead of confirming.
- Step 4 — Name the layer. Retrieval, reasoning, planning, or tool failure — one of the four layers above. Arjun's was planning: the agent needed a confirmation rule ("if two orders match, ask") before it was allowed to refund.
- Step 5 — Change one variable and re-run. Tighten the instruction, add the confirmation rule, or fix the tool's arguments, then re-run the same scenario. If the trace now shows the confirmation step, the fix is proven.
- Step 6 — Graduate when the console stops answering. The moment you need evaluations across hundreds of runs or a 180-day retention window, move to Langfuse or LangSmith. A free console that taught you the loop has already told you which paid feature you need.
Frequently asked questions
Is there a free LangSmith alternative?
Yes, with a scope warning. Langfuse is open source and free to self-host, and its cloud Hobby tier is free. VQ Agent Console is free with no seats and no trace meter, but it is a demo console for watching an agent loop — not a production observability platform with evaluations and retention. Free answers "why did this run fail"; production answers "why did any of our last 10,000 runs fail."
Why did my AI agent fail if the logs say everything succeeded?
Because HTTP logs measure requests, not decisions. A run can return a 200 status, a fluent answer, and a wrong action at the same time. You need the trace — prompt, tool calls, tool outputs, and the decision — to find the first wrong step. Check the four layers: retrieval, reasoning, planning, and tool execution.
How much does LangSmith cost for a small team?
Plus is $39 per seat per month with 10,000 base traces included, then per-trace usage (about $5 per 1,000 base traces) and paid retention upgrades. A five-person team at 20,000 traces a month lands around $245 a month before retention upgrades, on published October 2026 rates. The free Developer tier covers 5,000 traces a month for debugging.
Is Langfuse better than LangSmith?
Neither is better in the abstract. Langfuse is better when you want framework-agnostic tracing, self-hosting, and no per-seat meter. LangSmith is better when you build on LangChain/LangGraph and evaluations are your bottleneck. Langfuse's own pricing model favours Langfuse at high trace volumes; LangSmith's depth inside its own ecosystem is the counterweight.
Can I run an AI agent console locally with no data leaving my machine?
That is the right question for compliance-sensitive work, and the direction VQ Agent Core's local/offline DECIDE path points. For a full local stack today, self-hosted Langfuse or Phoenix keeps traces on your infrastructure — but budget the server and maintenance time, and confirm in writing whether any cloud feature phones home.
When should I stop using a free console and pay?
When you need any one of these: evaluations across many runs, dataset regression testing, alerting on behavioural drift, or retention beyond a demo window. At that point you are not buying a prettier trace — you are buying proof across thousands of runs, and that is what the paid platforms sell.
Related reading
- VisionQuantech AI services — the done-for-you AI agent services, including the AI Receptionist.
- AI voice agent vs human receptionist — the full head-to-head on cost, coverage, and what each model handles.
- AI receptionist for small business: the complete 2026 guide — costs, ROI, setup, and legal, for the business buying the agent in the first place.
References & further reading
- Soufian Azzaoui, "I tried LangSmith, Langfuse, Helicone, and Phoenix — here's what each gets wrong", DEV Community — dev.to
- "Langfuse vs LangSmith: Self-Hosting and LangGraph Depth", Quasa — quasa.io
- "Best AI agent observability tools in 2026: A comparison for production teams", Latitude — latitude.so
- "Langfuse vs LangSmith", Langfuse — langfuse.com
- "AI agent failure modes", Amplitude — amplitude.com
- Utibe Okodi, "Your AI Agent Just Failed in Production. Where Do You Even Start Debugging?", DEV Community — dev.to
Cite this article: Shivam Kumar (2026). Is There a Free LangSmith Alternative That Shows Why Your AI Agent Failed?. VisionQuantech. https://visionquantech.com/blog/free-langsmith-alternative-vq-agent-console.html